

A sale comes in during a launch, but the student doesn’t receive access to the course. The team finds out when a support message arrives. Robust integrations don’t prevent every failure: they make it possible to detect problems, contain them, and recover the process without having to review every step yourself.
A No-Code chain can work well while volume and exceptions are limited. The problem appears, however, when each action depends on the previous one and there is no clear response to an interruption. Adding more steps to that same chain doesn’t necessarily improve the system. Sometimes it just makes it harder to find where things broke.
Why a linear chain is no longer enough
Imagine a purchase connected to a sequence of actions: record the order, create the account, enroll the student, and send the access email. If the learning platform returns a temporary error, the sequence may stop after the payment is recorded. The sale exists, but access doesn’t. Without a visible status log, the team may not discover the discrepancy until the student complains.
Integrations can also fail because of API limits. For example, a tool may accept only a certain number of requests during a given period; if a launch concentrates many operations at once, some may be rejected or receive a rate-limit response. There are also race conditions: two processes arrive almost simultaneously and update a record in an unexpected order. Not everything has to fail to create a problem; it’s enough for a critical step to leave it unclear what happened.
Retrying an action seems simple, but it can repeat its effects. If the system runs an enrollment again without checking whether it already exists, it could create duplicates. Similarly, in recurring billing, repeating a charge without verifying the original event can lead to duplicate charges. Idempotency reduces this risk: the system recognizes a request that has already been processed and prevents the same action from being applied twice.
Robust integrations define what happens when something fails
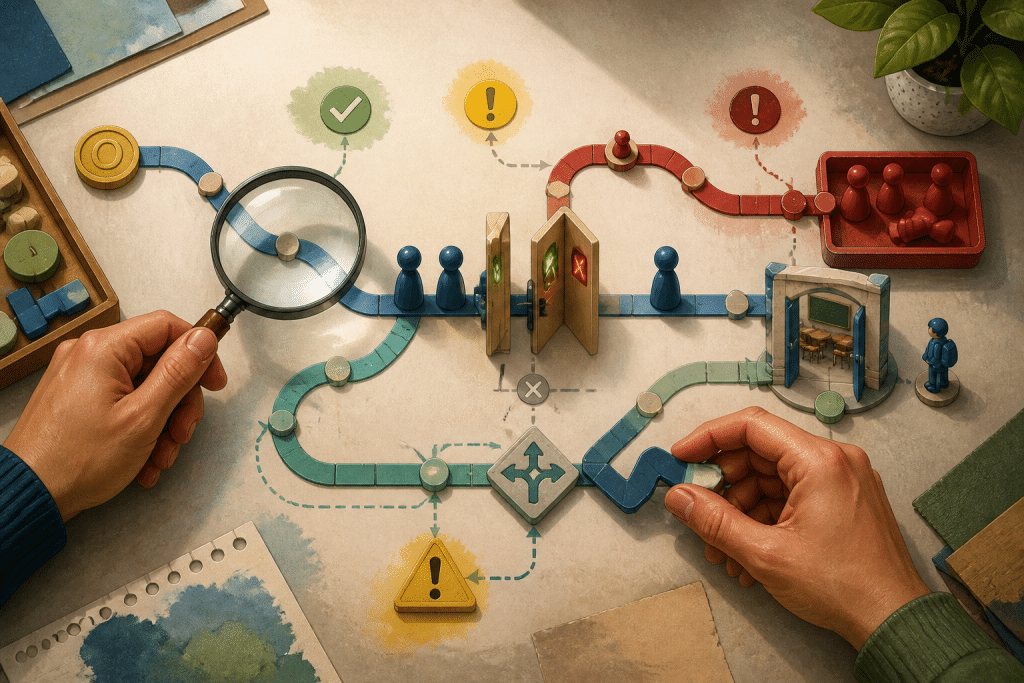
The architecture should distinguish between receiving an event, processing it, and confirming the result. For example, when someone makes a purchase, you can first record the order with a unique identifier and the status “enrollment pending.” The integration then tries to grant access and updates the status when it receives confirmation. If the platform doesn’t respond, the order remains visible as pending instead of disappearing inside an opaque chain.
That status makes it possible to take specific action. The system can retry temporary errors in a controlled way, alert the team when a limit is exceeded, and provide a manual path for exceptional cases. In addition, logs should show which event arrived, what action was attempted, and what result the tool returned. That way, support doesn’t have to reconstruct the story from scattered emails and screenshots.
This doesn’t mean you need to replace all your No-Code tools with custom software. You can keep using them where they provide speed, such as for low-risk internal tasks. By contrast, processes that affect access, money, or continuity of service deserve closer scrutiny. The strategic decision isn’t to automate everything; it’s to give greater control to operations whose interruption harms the student or the business.
Apply the PAHP Method to the purchase and access workflow
Exploration: Follow the actual journey from payment to access confirmation. Talk to the people who manage enrollment and support, and review both a normal purchase and an exception. Don’t limit yourself to the idealized diagram: look for the manual steps the team takes when something is left pending.
Diagnosis: Identify dependencies, single points of failure, and actions that could be repeated. Check whether each system confirms its results, whether request limits exist, and who receives an alert when a task stops. During a launch, it matters what happens to simultaneous enrollments; for recurring billing, you need to distinguish a confirmed charge from an event received twice.
In-depth investigation: Review the data and events available in each tool. Confirm which identifiers can link the payment to the student, what responses the API returns, and how long each step may take. This review helps prevent designing retries blindly or assuming that two platforms interpret an event the same way.
Action plan: Prioritize according to the impact on the student and the operation. It may make sense to start by securing enrollment and the access notification before automating less critical administrative tasks. Define statuses, validations, alerts, retry rules, and a manual intervention path. Also, assign someone to take responsibility for each case the automation can’t resolve.
Execution: Implement changes in stages and verify each result. Test a normal purchase, a repeated event, and a temporarily failed response before expanding the workflow. Then review the logs and alerts with the team that will handle exceptions. An integration isn’t ready just because it completes the expected path; it must also show how to recover when something is interrupted.
Recovery also protects the student experience
At a digital academy, a technical error isn’t just an issue between applications. It can prevent someone from starting training they’ve already paid for or leave the team searching for what happened. That’s why visible statuses and recovery paths reduce the gap between internal operations and the student experience. They also prevent the founder from being the only person able to unblock the process.
Before adding another step to an automation, define how you’ll know it failed, what will prevent it from happening again, and who can intervene. That decision separates a chain that works only when everything goes right from a system designed to recover. Design operations so the team can resolve exceptions without depending on you to monitor every sale.